Evaluate agents your way.
0 Followers
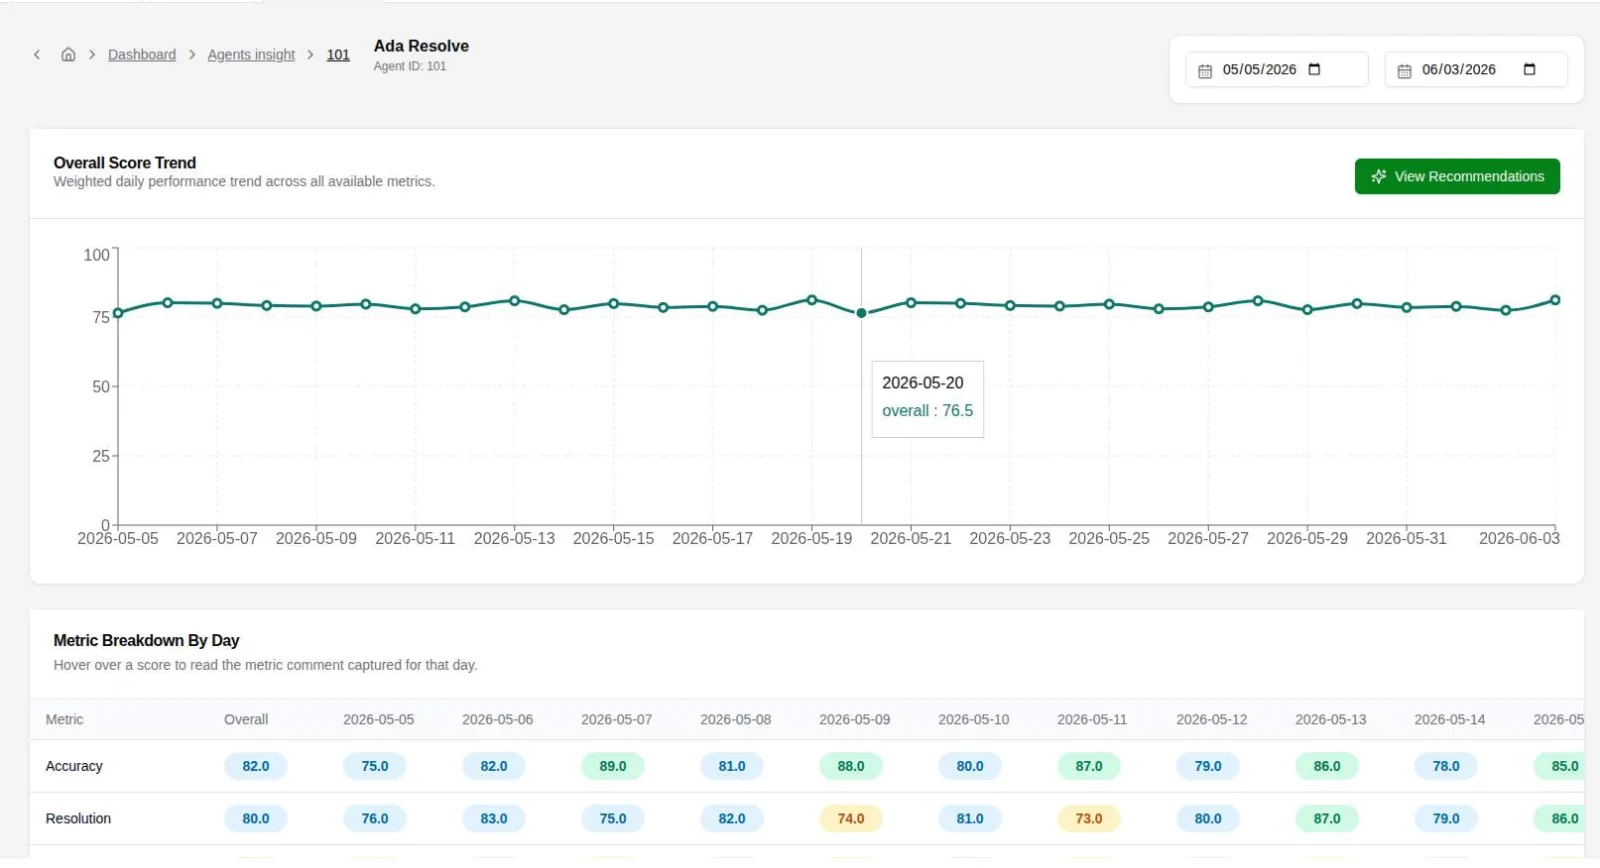
A quality evaluation layer for teams running AI agents, humans, or both. Most quality programs rely on borrowed standards or opaque scores. Here, you define the metrics in plain language—resolution quality, CSAT, compliance, tone, escalation discipline—and every conversation is scored against them. Standards are role-based, ensuring appropriate evaluation for roles like billing specialists or escalation engineers.
Please login to review
No reviews yet. Be the first to share your experience!